Pavan Dangeti

Pavan Subramanyam Sai Kumar Dangeti

AI/ML Engineer: models measured against honest baselines

AI/ML Engineer Intern at Sacha Global · Final-year B.Tech, Pragati University

I build services, ML models and LLM systems, and publish how each one was measured, including when the simple baseline wins.

Looking for Software Development Engineer (SDE), LLM Engineer and AI/ML Engineer roles: full-time from 2027, and internships. India, open to relocation and remote.

AI/ML Engineer

AI/ML

An AI/ML Engineer takes a model from raw data to production, owning the features, training, evaluation, serving and monitoring. The best ones measure against a simple baseline on leakage-safe splits, ship what actually wins, and notice drift before users do.

How I work in this role

Multilingual scam detection for Indian SMS and WhatsApp, measured against a cheap baseline

Flags payment scams in code-mixed Indian SMS and WhatsApp messages, for the people who receive them.

Raised scam-detection F1 from 0.908 to 0.998 on a largely synthetic 1,554-message validation set by fine-tuning XLM-R with adversarial augmentation.

AI/MLLLMShipped

Scam F1, validation
0.998
Baseline: TF-IDF + logistic regression 0.908
XLM-R base with adversarial augmentation on a 1,554-message validation split of a largely synthetic corpus, threshold 0.5, 95% CI 0.995–1.000 (results/evaluation_with_ci_aug.json). Evidence about the method, not real traffic
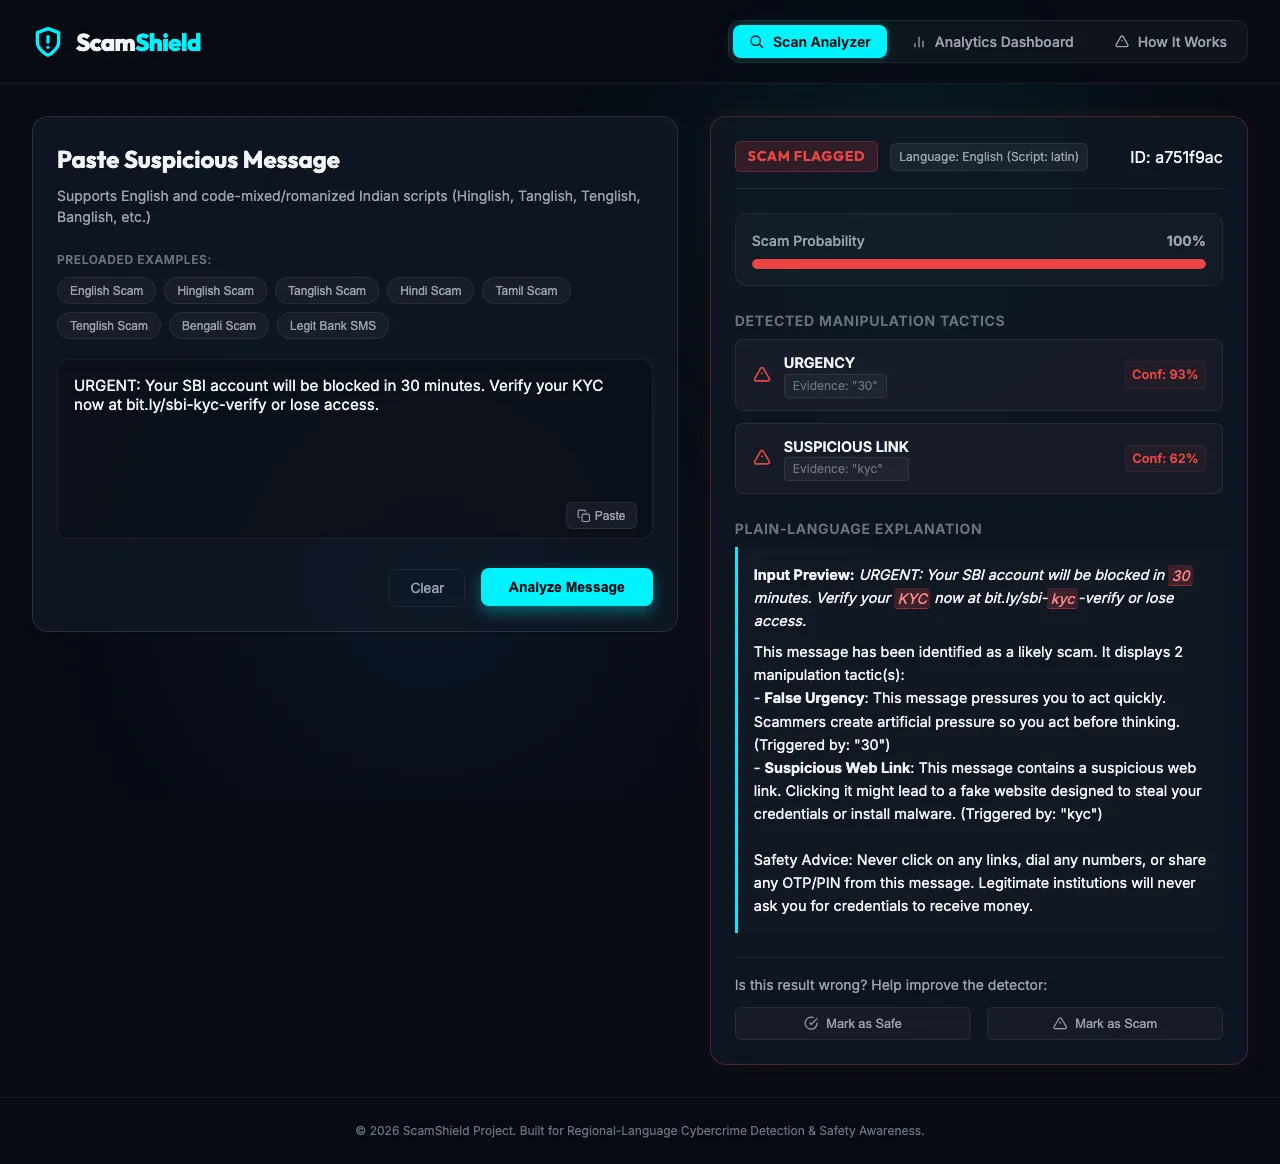
ScamShield flagging an example English scam message, with its urgency and suspicious-link tactics and the evidence for each

A recommender whose most important finding is that recency-weighted popularity wins

Recommends each shopper's next products from a catalogue of over a million items, with a reason for each.

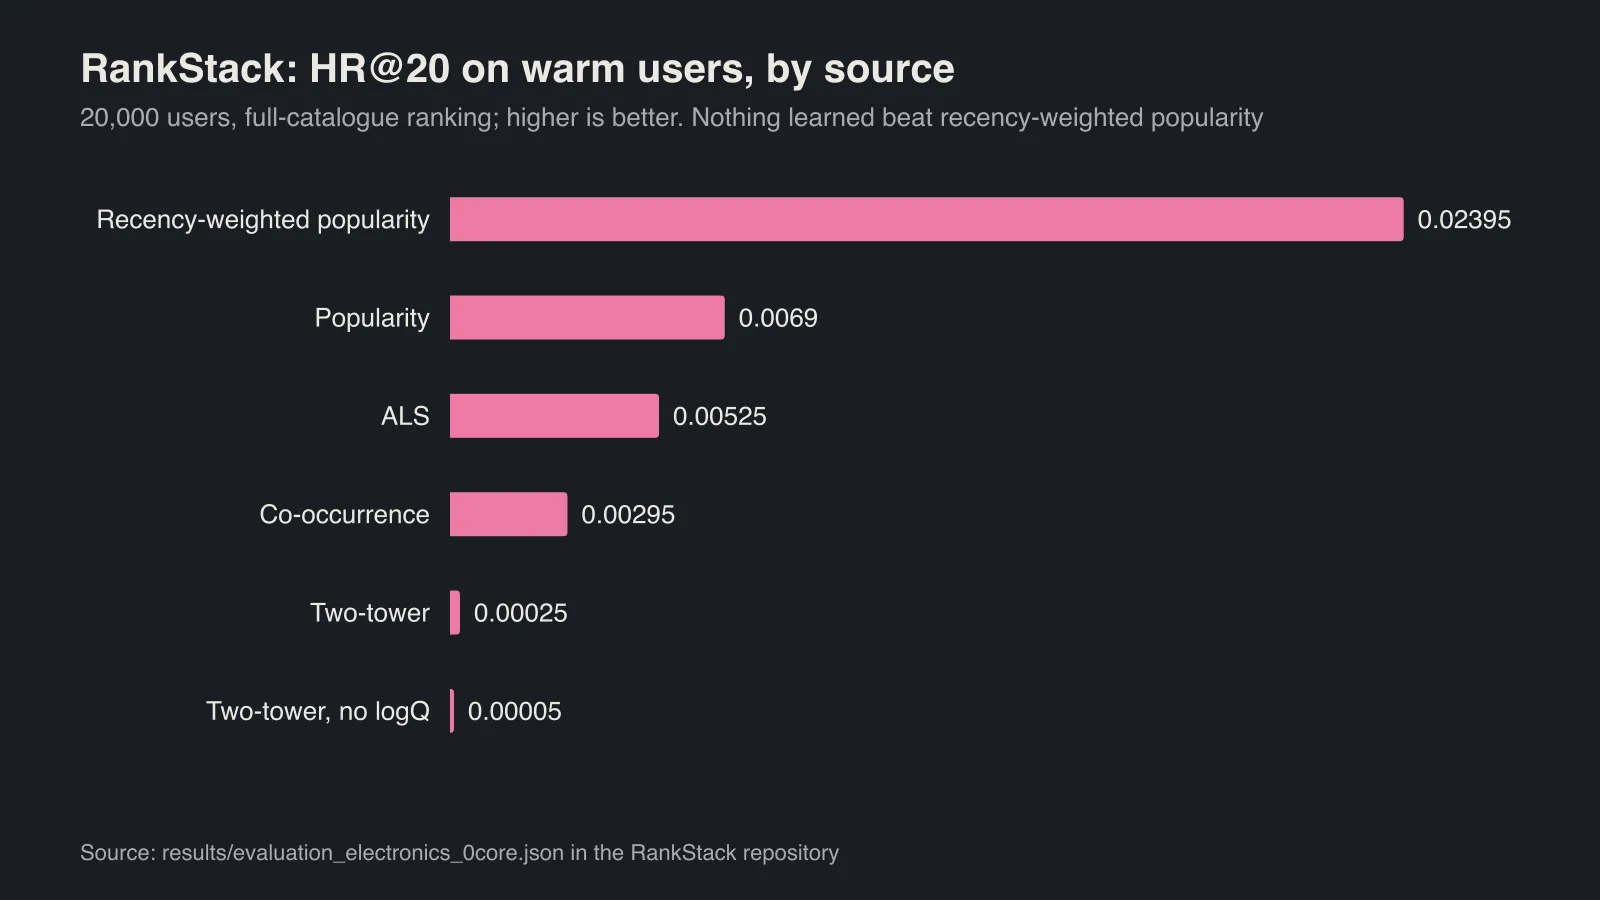
Showed that recency-weighted popularity (HR@20 0.024 on 20,000 warm users) beat every learned model, including two-tower at 0.00025, by evaluating on a strict global timeline.

AI/MLIn progress

Warm-user HR@20, best source
0.024
Baseline: Two-tower 0.00025, ALS 0.0053
Recency-weighted popularity on 20,000 warm users, exact full-catalogue ranking, one held-out target each (results/evaluation_electronics_0core.json); every learned model's paired-bootstrap difference against it excludes zero
Bar chart of RankStack's HR@20 on warm users by source: recency-weighted popularity 0.02395, popularity 0.0069, ALS 0.00525, co-occurrence 0.00295, two-tower 0.00025

Remaining-useful-life prediction for turbofan engines, with the test engines still unopened

Predicts how long each turbofan engine has before maintenance, with an honest error bar. A research demonstration.

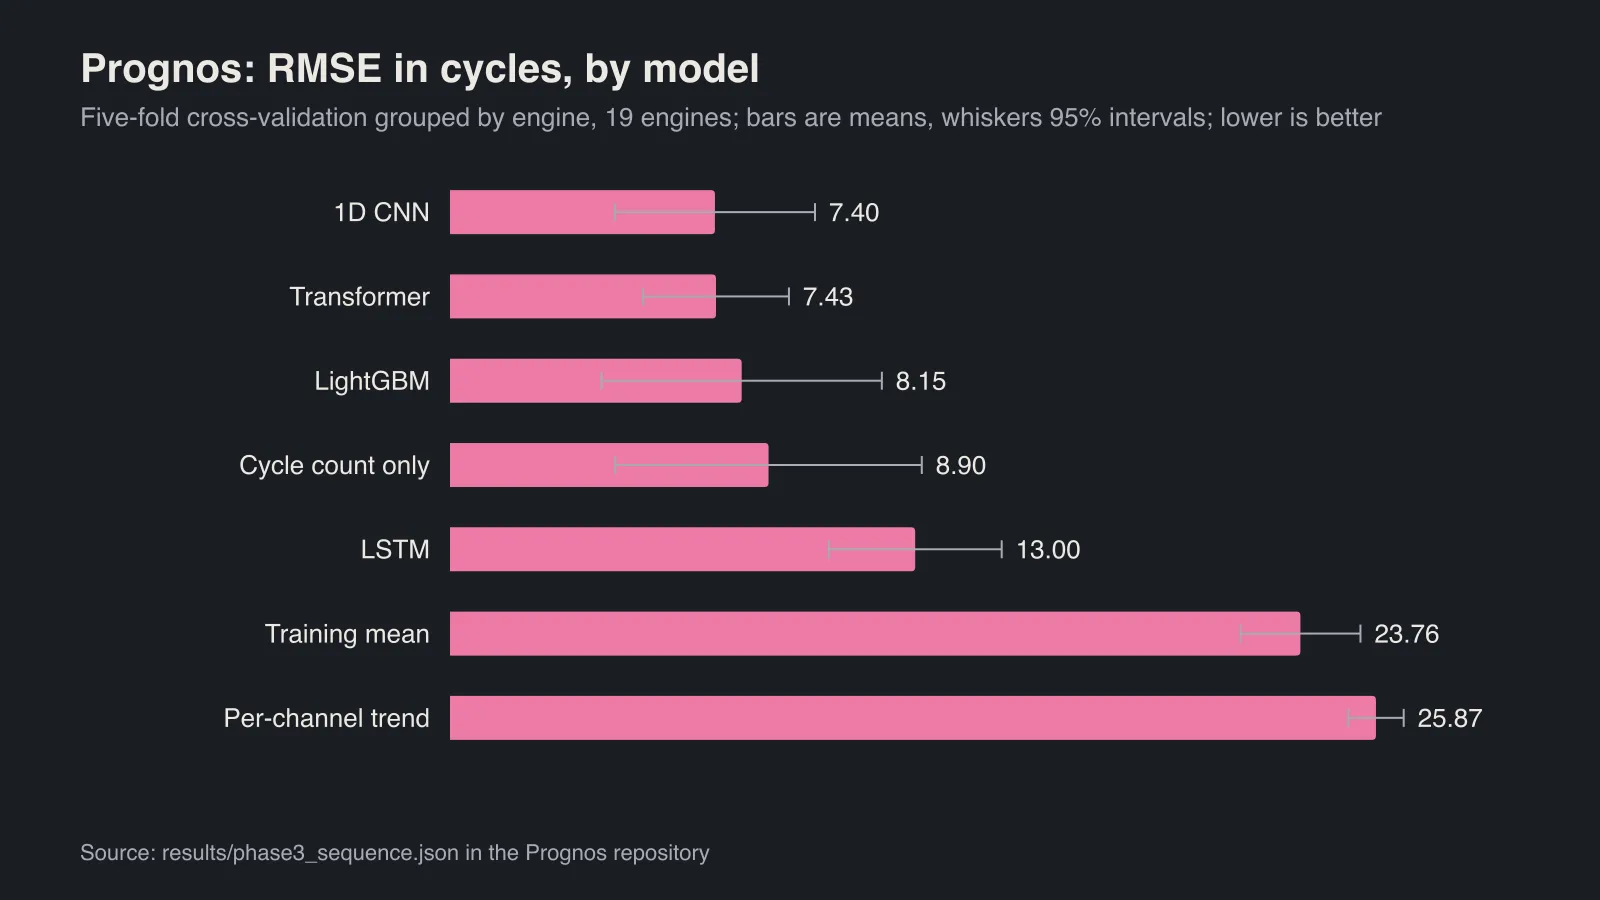
Reduced remaining-life error to 7.40 cycles RMSE, against 8.90 for cycle count alone, in cross-validation over 19 engines, by training a 1D CNN; 10 test engines are unscored.

AI/MLIn progress

RMSE, best model (cycles)
7.40
Baseline: 8.90 from cycle count alone, with no sensors
1D CNN, 5-fold cross-validation grouped by engine over 19 engines (results/phase3_sequence.json), 95% interval 4.61–10.20 resampled by engine; the 10-engine test group has not been scored yet
Bar chart of Prognos RMSE by model with 95% intervals: 1D CNN 7.40, Transformer 7.43, LightGBM 8.15, cycle count only 8.90, LSTM 13.00, training mean 23.76, per-channel trend 25.87

All projects

Software Development Engineer (SDE)

SDE

A Software Development Engineer designs, builds and runs the services a product depends on, and owns their correctness, latency and cost from design review to production. The best ones build systems that stay correct and fast at scale and under failure, and prove it with tests and measurements rather than assumptions.

How I work in this role

LLM Engineer

LLM

An LLM Engineer turns language models into products people can rely on, owning model choice, prompts, retrieval and output quality in production. The best ones treat evaluation as part of the product: held-out test sets, guardrails enforced in code, and latency and cost kept under control.

How I work in this role

Explore